


koffset: consumer lag without the consumer
First written January 2026, last updated September 2026.
Broker lag metrics tell you when a consumer committed, not how far behind it is. koffset measures consumer lag in time, not just offsets, without running a consumer.
Introduction
In early 2026 we started koffset, a project inspired by growing frustrations with consumer group monitoring. Issues such as archived or inactive projects, scalability limitations, stale metrics, and hanging endpoints ultimately pushed us down this path.
Consumer lag metrics obtained directly from the broker are inherently stale. They tell you when consumers committed offsets, and nothing about the actual processing lag. In addition, if the metric collection is asynchronous from metric retrieval, the reported lag can be even worse, depending on the cadence of refresh and scraping operations.
That led to one of our major goals for this application: fetch offsets as close as possible to scrape time, without doing lag retrieval and calculation inside the scrape request itself.
Burrow and the Prometheus-style Kafka lag exporters cover the same ground: they read committed offsets and topic end offsets through the admin API and export the difference. koffset adds three things on top of that pattern: collection timed to the scrape interval so the numbers are fresh, lag expressed in time as well as offsets, and group-level status and staleness signals alongside the lag.
Key features
- Adaptive metric collection - Automatically adjusts collection frequency to align with the scrape interval, keeping metrics as fresh as possible. Keeping collection of metrics and serving of metrics in sync is critical to avoid stale metrics.
- 100% Admin Client-based - Using a consumer client to fetch timestamp-based offset metrics provides more accuracy, but it introduces more overhead than we were willing to accept. This project doesn't use a Kafka consumer. We didn't benchmark whether a layer of consumers for timestamp collection would scale; we went with that assumption.
- Lean Java application - Starts in seconds with a memory footprint under 200 MB (testing and validation are still ongoing). A GraalVM build is also available, using approximately 25 MB of memory. There is no framework, just primarily kafka-client, netty, logback, and slf4j.
- Time-based lag - Timestamps matter when humans are trying to understand what’s happening in a system. This is where a lot of experimentation and effort went into this application. We’re sure these algorithms will need to be improved over time.
- Group-level metrics - Visibility into group status, members, and coordinators is critical and often overlooked. We've found this information lacking in other lag collection tools. When a client is slow, you can compare the consumer group's view with the broker's.
- Staleness detection - Knowing whether an offset isn’t moving because a producer has stopped publishing versus a dead consumer is essential. We haven't seen this in other lag tools, and time will tell how useful it is, or whether this information can easily be determined by other metrics.
Grafana Dashboard
A sample Grafana dashboard is included with the project.
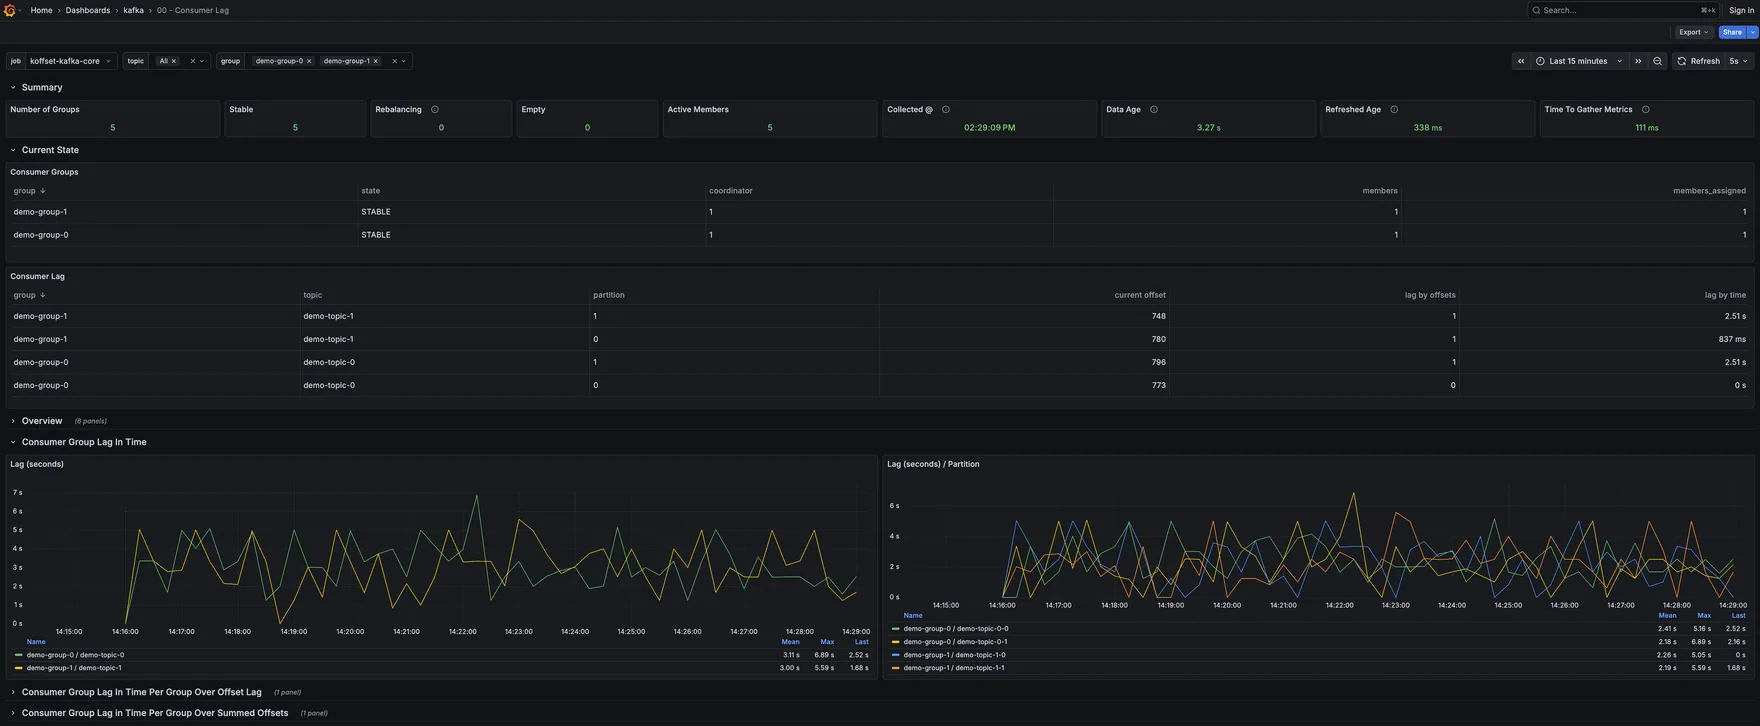
The dashboard JSON ships with a complete demo docker-compose setup.
Developer Details
The project provides three ways to build a container for this application:
build-docker.sh- A multi-stage build used to compile the application and build the image. This is the same image built by the GitHub Actions workflow.build-docker-dev.sh- A single-stage build that uses the local build from your laptop, a fast way to get a new container built for development.build-docker-native.sh- A multi-stage build using GraalVM. It uses the native configuration from anative.shrun of the application. Work is continuing to improve the native image inclusions (e.g. SASL authentication).
There is also a run.sh script to run the application without building a distribution. It uses the Gradle classpath and provides a similar feel to Spring Boot's bootRun Gradle task.
Next Steps of Development
- Load/Scale/Performance testing - Some preliminary testing has been done, but we want a more formal process that gives anyone considering
koffsetassurance it can handle their cluster. - Multiple Cluster Support - This is something we’ve seen in other collection tools, but we’re still deciding if it is something to support. We typically spin up administration tools per cluster (unless they have a front-facing UI).
- GraalVM Native Image Improvements - as mentioned above.
- Metric Validation - a way to validate that derived metrics are accurate. Focusing on unit tests that verify the math is computed as designed. Future work will validate they hold up in production.
Source and Image
The GitHub repository is at kineticedge/koffset; the README.md has the complete details. The project is licensed under Apache 2.0, and dependencies are intentionally minimal to reduce the impact of CVEs when they arise. You can pull the release image from GitHub Container Registry, ghcr.io/kineticedge/koffset-exporter:0.0.1.
docker pull ghcr.io/kineticedge/koffset-exporter:0.0.1Contact
We work with teams in their Kafka application development as well as improving their operations. koffset came out of that work. If you need help building or operating Kafka systems, contact us.
Working on something like this?
Start a Conversation